
如何使用 Java 从 PDF 中提取内容
问题描述
如何使用 Java 从 PDF 中提取内容。
解决方案
以下是使用 Java 从 PDF 中提取内容的程序。
import java.io.File;
import java.io.FileInputStream;

import org.apache.tika.metadata.Metadata;
import org.apache.tika.parser.ParseContext;
import org.apache.tika.parser.pdf.PDFParser;
import org.apache.tika.sax.BodyContentHandler;

public class ExtractContentFromPDF {
   public static void main(String[] args) throws Exception {
      BodyContentHandler handler = new BodyContentHandler();
      Metadata metadata = new Metadata();
      FileInputStream inputstream = new FileInputStream(new File(
         "C:/tika/pdfExample.pdf"));

      ParseContext pcontext = new ParseContext();

      //使用 PDF 解析器解析文档
      PDFParser pdfparser = new PDFParser();
      pdfparser.parse(inputstream, handler, metadata,pcontext);

      //获取文档的内容
      System.out.println("Contents of the PDF :" + handler.toString());

      //获取文档的元数据
      System.out.println("Metadata of the PDF:");
      String[] metadataNames = metadata.names();

      for(String name : metadataNames) {
         System.out.println(name+ " : " + metadata.get(name));
      }
   }
}
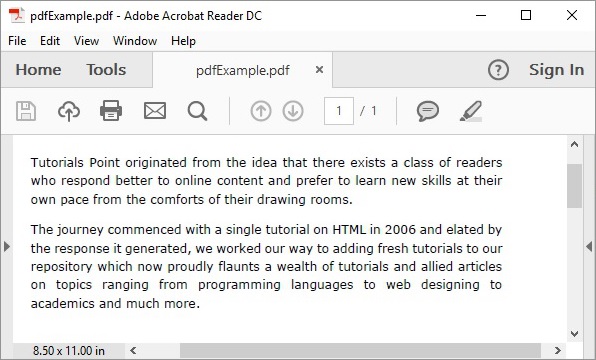
输入
输出
Contents of the document:Sheet1
   ID   NAME     BRANCH     PERCENTAGE       EMAIL
   1     Ram       IT          85         ram123@gmail.com
   2    Rahim      EEE         95         rahim123@gmail.com
   3    Robert     ECE         90         robert123@gmail.com

Metadata of the document:
date: 2017-05-19T09:35:57Z
extended-properties:AppVersion: 16.0300
meta:creation-date: 2015-06-05T18:17:20Z
extended-properties:Application: Microsoft Excel
extended-properties:Company:
Creation-Date: 2015-06-05T18:17:20Z
dcterms:created: 2015-06-05T18:17:20Z
Last-Modified: 2017-05-19T09:35:57Z
dcterms:modified: 2017-05-19T09:35:57Z
Last-Save-Date: 2017-05-19T09:35:57Z
Application-Version: 16.0300
protected: false
meta:save-date: 2017-05-19T09:35:57Z
Application-Name: Microsoft Excel
modified: 2017-05-19T09:35:57Z
publisher:
Content-Type: application/vnd.openxmlformats-officedocument.spreadsheetml.sheet
dc:publisher:
java_apache_tika.html

