如何在 Python 中使用 Selenium 和 BeautifulSoup 解析网站?
seleniumautomation testingtesting tools更新于 2026/2/3 6:37:17
我们可以使用 Python 中的 Selenium 和 BeautifulSoup 解析网站。网页抓取 (Web Scraping) 是一种从网页中提取内容的技术,广泛应用于数据科学和指标准备。在 Python 中,可以使用 BeautifulSoup 包实现。
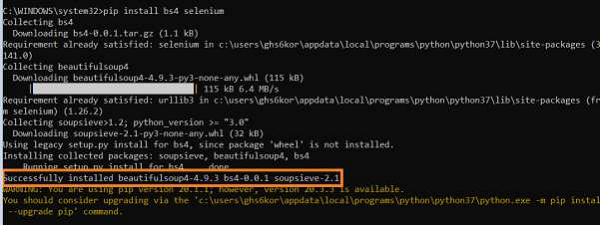
要将 BeautifulSoup 与 Selenium 一起使用,我们应该运行命令 −
pip install bs4 selenium
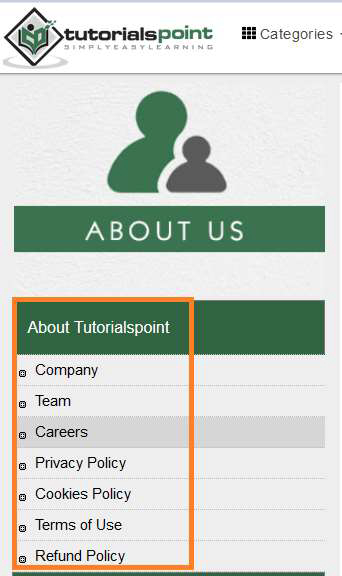
让我们抓取页面上显示的以下链接 −
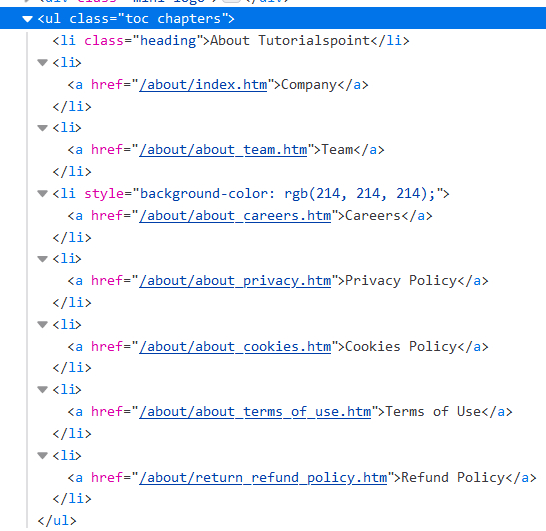
然后研究上述元素的 html 结构−
示例
from selenium import webdriver
from bs4 import BeautifulSoup
#chromedriver.exe 的路径
driver = webdriver.Chrome (executable_path="C:\chromedriver.exe")
#启动浏览器
driver.get ("https://www.tutorialspoint.com/about/about_careers.htm")
#以 html 格式显示整个页面内容
s = BeautifulSoup(driver.page_source, 'html.parser')
#使用 BeautifulSoup 方法访问特定的 ul 元素
l = s.find('ul', {'class':'toc chapters'})
# 获取 ul 下的所有 li 元素
rs = l.findAll('li')
for r in rs:
# 获取 li 元素的文本
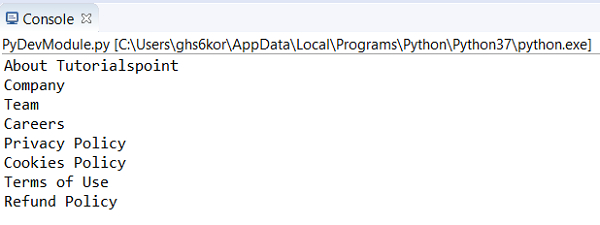
   print(r.text)
输出