如何使用 webdriver 获取元素的所有后代?
seleniumautomation testingtesting tools更新于 2026/2/11 12:07:17
我们可以使用 Selenium webdriver 获取元素的所有后代。首先,我们需要借助 id、class、name、xpath 或 css 等定位器来识别父元素。然后,我们必须使用 findElements(By.xpath()) 方法识别后代。
我们可以从父元素中找到后代,方法是将其与父元素进行本地化,然后将 ( .//*) 作为参数传递给 findElements(By.xpath())
语法
element.findElements(By.xpath(".//*"))
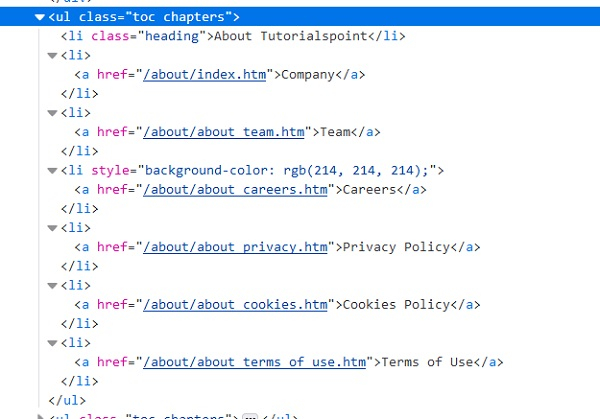
让我们在下面的 html 代码中识别 ul 元素后代的标签名−
示例
import org.openqa.selenium.By;
import org.openqa.selenium.WebDriver;
import org.openqa.selenium.WebElement;
import org.openqa.selenium.chrome.ChromeDriver;
import java.util.concurrent.TimeUnit;

public class DescendantElements{
   public static void main(String[] args) {
System.setProperty("webdriver.chrome.driver","C:\Users\ghs6kor\Desktop\Java\chromedriver.exe");
      WebDriver driver = new ChromeDriver();
      driver.manage().timeouts().implicitlyWait(5, TimeUnit.SECONDS);
      driver.get("https://www.tutorialspoint.com/about/about_careers.htm");
      // 识别元素
      WebElement p=driver.findElement(By.xpath("//ul[@class='toc chapters']"));
      // 使用 xpath 中的 .//* 表达式识别后代
      List d = p.findElements(By.xpath(".//*"));
      // 迭代后代
      for ( WebElement j : d ) {
         //getTagName() to descendant tags
         System.out.println(j.getTagName());
      }
      driver.close();
   }
}
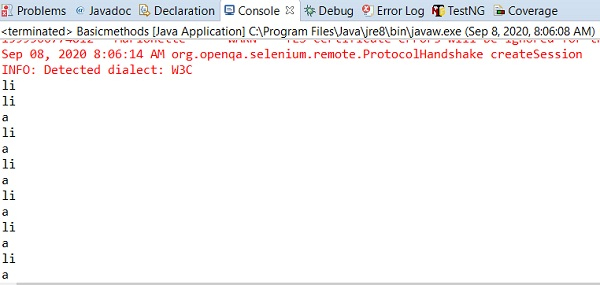
输出